Need to convert XML to Excel? You are dealing with one of the oldest data formats on the web — and one of the most stubborn. XML files show up everywhere: e-commerce product feeds, accounting software exports, government open-data portals, sitemap files, RSS feeds, and legacy enterprise systems that have been running since before JSON was fashionable. But while XML is excellent for machines, it is miserable for humans to read in raw form, and double-clicking an .xml file usually opens it in a browser as an unreadable tree of angle brackets. This guide shows you five free, practical ways to turn XML into a clean, readable spreadsheet: a browser-based xml to xlsx converter, Excel’s built-in Developer tab XML Maps, the Power Query XML import, a Python script for complex files, and free workarounds for Google Sheets and Mac users.
You will also learn how XML is actually structured — elements, attributes, nesting, and namespaces — because understanding the structure is what separates a clean import from a mangled one. We will walk through a complete worked example (a product catalog), troubleshoot the classic failures (blank columns, namespace headaches, repeating elements that refuse to become rows), and finish with pro tips that keep your conversions reliable. Whether you are an accountant in Chicago importing a QuickBooks-style export, a marketer in London wrangling a Google Shopping feed, or a researcher in Sydney parsing an open-data dump, these steps work the same on Excel 2016 through Microsoft 365.
What Is XML? Understanding the Format Before You Convert
XML stands for eXtensible Markup Language. It is a text format for describing hierarchical data with tags — angle-bracket labels like <product> — that you get to invent yourself, unlike HTML’s fixed set of tags. A simple XML document looks like this:
<catalog>
  <product id="P1001">
    <name>Wireless Mouse</name>
    <price currency="USD">29.99</price>
    <stock>340</stock>
  </product>
  <product id="P1002">
    <name>USB-C Hub</name>
    <price currency="USD">49.99</price>
    <stock>120</stock>
  </product>
</catalog>
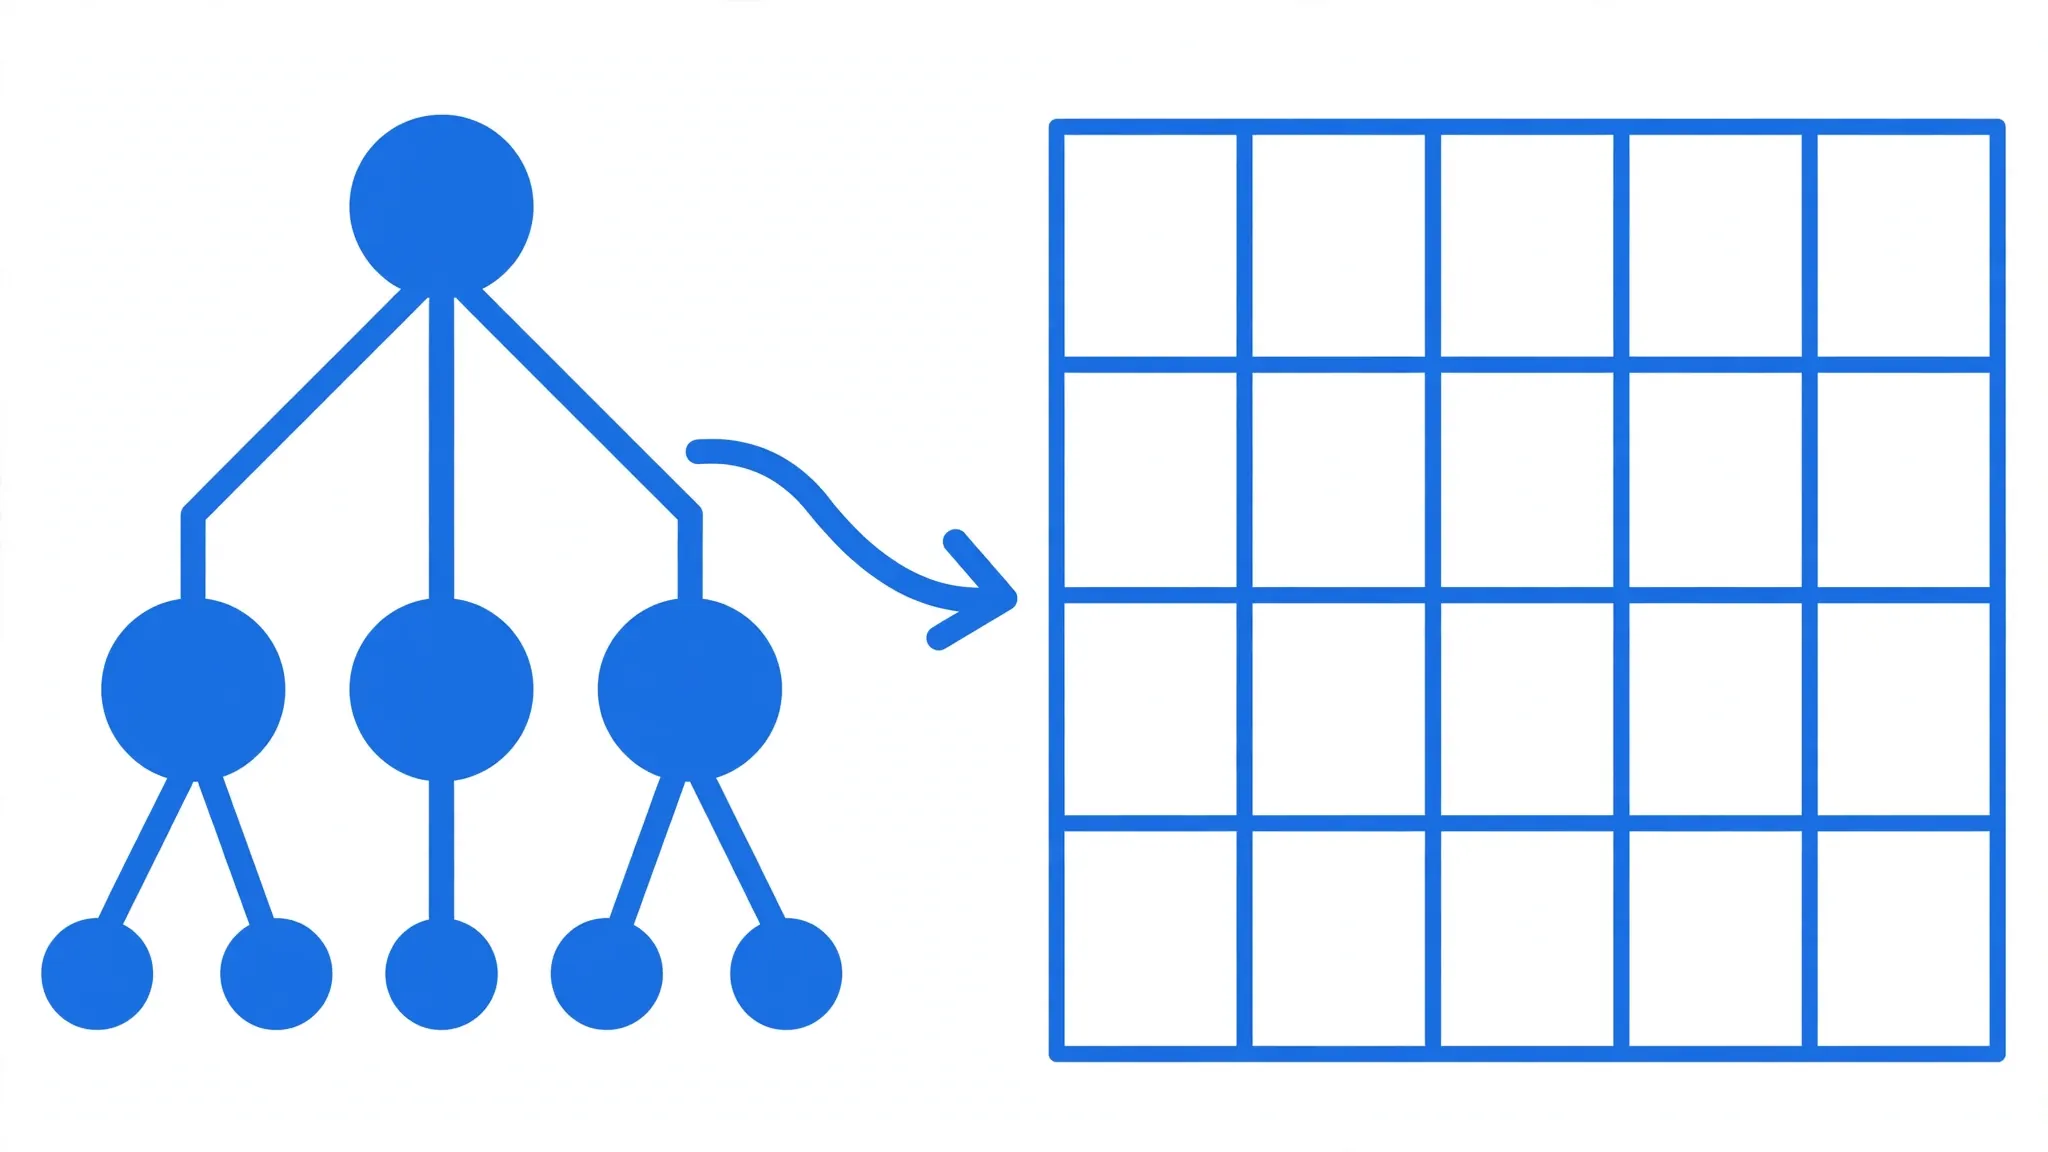
Three concepts matter for conversion. Elements (<name>) become columns or rows. Attributes (id="P1001", currency="USD") are metadata attached to elements — good converters expose them as their own columns. Nesting (products inside a catalog) is the hierarchy you must flatten, exactly like nested JSON. The repeating element — here <product> appearing twice — is the key discovery: each repetition becomes one spreadsheet row, and its children become the columns.
XML also has two features that regularly sabotage imports: namespaces (prefixes like <g:price> used in Google Shopping feeds) and schemas (XSD files that formally describe the structure). Namespaces confuse naive converters into producing blank columns; schemas, on the other hand, are a gift — Excel can read an XSD to build a perfect XML Map automatically.
Method 1: Convert XML to Excel with a Free Online Tool
For a one-off file with a straightforward structure, a browser converter is the fastest path — no Excel expertise required.
- Open the converter. Head to the free converter on csvtoexcel.site/, which detects repeating XML elements and turns them into rows, entirely in your browser.
- Upload your .xml file. Drag and drop it into the upload area. If the file is huge (tens of megabytes), the Power Query or Python methods below will be more reliable.
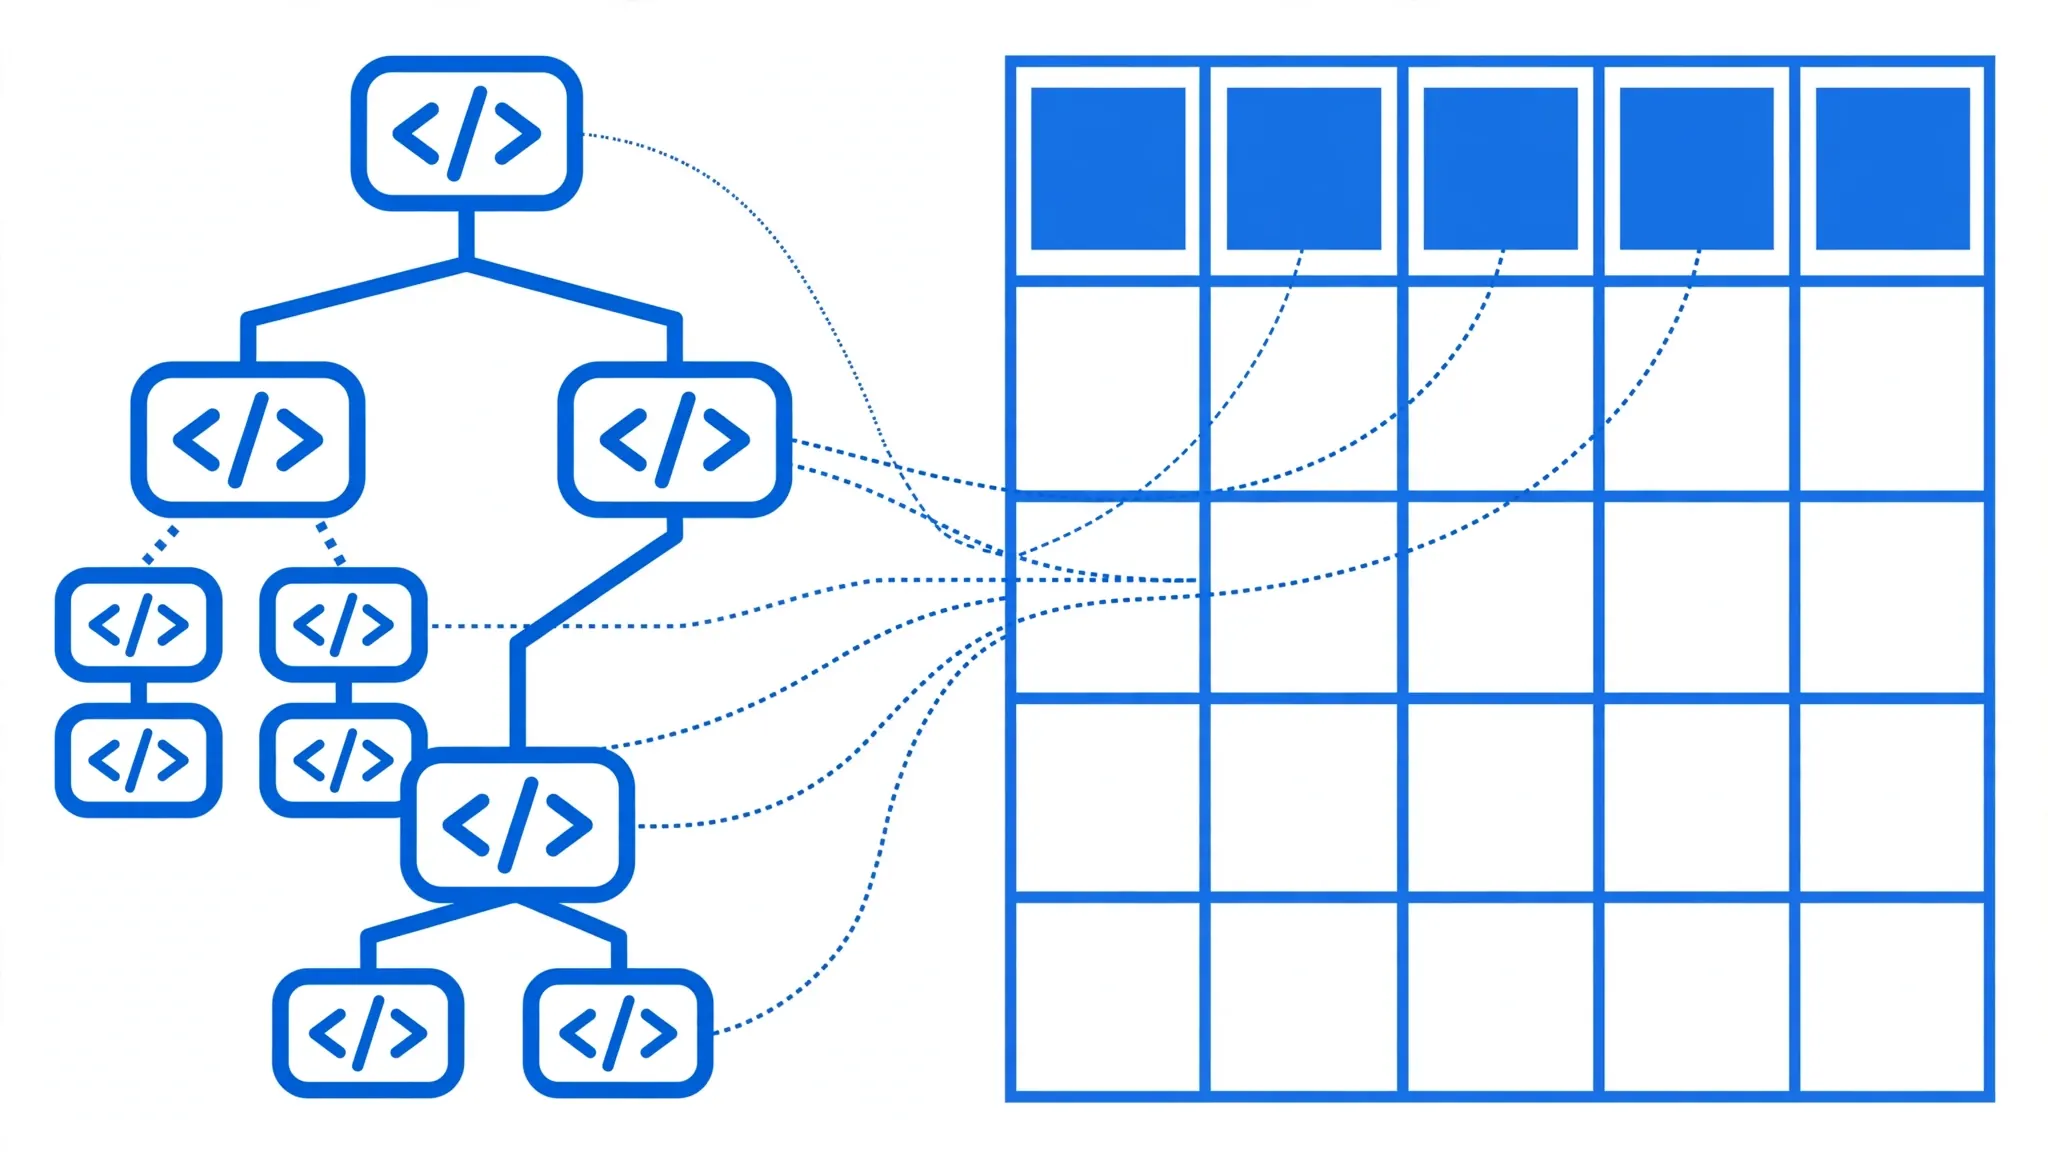
- Check the preview. Confirm that the repeating element was detected (you should see one row per record), that attributes appear as columns, and that nested elements were flattened sensibly.
- Download the .xlsx and open it in Excel or Google Sheets to verify.
Method 2: Open XML in Excel via the Developer Tab (XML Maps)
Excel has a purpose-built XML engine hiding in the Developer tab — the most precise way to open XML in Excel when you want control over exactly which element lands in which cell. It is also refreshable: point the map at a new XML file and the sheet updates.
- Enable the Developer tab. File → Options → Customize Ribbon → check Developer → OK. (On Mac: Excel → Preferences → Ribbon & Toolbar → check Developer.)
- Add an XML Map. On the Developer tab, click Source. In the XML Source pane, click XML Maps → Add, select your .xml file (or its .xsd schema if you have one), and click OK.
- Drag elements onto the sheet. The pane shows the XML tree. Drag the repeating element (e.g.,
product) onto cell A1 — Excel creates a table with one column per child element. Drag any attributes you need into adjacent cells. - Import the data. Click Developer → Import, select the XML file, and choose where to place the data. Each repetition of the element becomes a table row.
- Refresh later. When the source XML updates, click Developer → Refresh Data (or Data → Refresh All) to re-import.
Two details make or break XML Maps. First, always drag the repeating element, not its parent — dragging catalog gives you one row, dragging product gives you a proper table. Second, if Excel warns that the XML is “not mappable” or infers a schema you disagree with, supply the real XSD schema at step 2 if you have one; inferred schemas sometimes guess data types wrong (turning ID codes into numbers, for instance). A useful middle ground: let Excel infer the schema, import once, and inspect the resulting table’s column types — if product codes arrived as numbers or dates shifted format, delete the map, tweak the source, and re-add it with the corrected XSD. Getting the map right once pays off every time the feed refreshes, because the mapping — unlike a one-off converter run — remembers exactly which element belongs in which column.
Method 3: Import XML into Excel with Power Query
Power Query is the most forgiving way to import XML — it handles namespaces, deep nesting, and messy real-world feeds with a visual editor, and the import is fully refreshable.
- Go to Data → Get Data → From File → From XML and select your file.
- The Navigator shows the XML structure. Click into the repeating element (the table icon next to
product, not the top-levelcatalog) to preview rows. - Click Transform Data. In the editor, use the expand icon on nested columns to flatten child elements into columns. Attributes appear as fields — keep the ones you need, remove the rest.
- If a column holds a list (e.g., multiple
<category>tags), expand it with Expand to New Rows to get one row per value. - Set data types explicitly — especially Text for IDs, SKUs, and codes with leading zeros — then Close & Load.
g:price). If expanding yields blanks, expand one level at a time and watch which level actually holds the values — the data is almost always there, just one level deeper than you expected.Like the Developer-tab method, this query refreshes with one click when the XML updates, making it ideal for recurring feeds — price lists, inventory exports, or daily data drops. Our Power Query guide covers the editor’s full toolkit.
Method 4: Convert XML to Excel with Python
When XML is deeply nested, enormous, or needs serious cleaning, Python’s xml.etree.ElementTree plus pandas gives you total control:
import xml.etree.ElementTree as ET
import pandas as pd

tree = ET.parse("catalog.xml")
root = tree.getroot()

rows = []
for product in root.findall("product"):   # the repeating element
    rows.append({
        "id": product.get("id"),           # attribute
        "name": product.findtext("name"),
        "price": float(product.findtext("price")),
        "currency": product.find("price").get("currency"),
        "stock": int(product.findtext("stock")),
    })

df = pd.DataFrame(rows)
df.to_excel("catalog.xlsx", index=False)
For namespaced XML, pass a namespace map: root.findall("g:product", {"g": "http://..."}) — the URI comes from the xmlns:g="..." declaration at the top of the file. For very large files, use ET.iterparse to stream element-by-element instead of loading the whole tree into memory. And for batch jobs, loop over a folder of XML files exactly like the CSV-to-Excel Python pattern — the export half is identical.
Method 5: Google Sheets and Other Free Routes
Google Sheets has no native XML import, but the workarounds are easy. Option A: convert the XML to XLSX with the free online converter, then File → Import → Upload in Sheets. Option B: for XML published at a URL (like an RSS feed), the IMPORTXML function pulls values directly: =IMPORTXML("https://example.com/feed.xml", "//item/title") — the second argument is an XPath expression describing which elements to grab. XPath looks intimidating but //product/name simply means “every name inside every product,” which covers most needs.
On a Mac without Excel, Apple Numbers cannot import XML directly — convert to XLSX first in the browser, then open in Numbers. LibreOffice Calc opens simple XML via its own filters but struggles with namespaces; again, converting first is the smoother path.
Sitemaps and RSS feeds: XML you meet in the wild
Two XML flavors deserve special mention because people encounter them constantly. An XML sitemap (sitemap.xml) lists a website’s pages with URLs, last-modified dates, and priorities — SEO specialists convert these to spreadsheets to audit thousands of URLs, check for stale dates, or find pages missing from the index. The repeating element is <url>, and Power Query turns a 50,000-URL sitemap into a filterable table in under a minute. An RSS or Atom feed is XML too, with <item> (or <entry>) as the repeating element — content teams import feeds into Excel to analyze publishing frequency, track headlines, or archive articles. Both are usually available at a plain URL, so Power Query’s From Web option (Data → Get Data → From Other Sources → From Web) can pull them directly without downloading a file first. Just paste the feed URL, and the same expand-and-flatten workflow applies.
Understanding XML Structure: Elements, Attributes, and Nesting
A clean conversion starts with reading the XML’s shape. Open the file in a text editor (not a browser) and identify four things:
The repeating element
Find the element that appears many times at the same level — <product>, <order>, <item>. This becomes your row grain. Everything else hangs off it.
Attributes vs child elements
Both carry data, but tools treat them differently. <product id="P1001"> stores the ID as an attribute; <id>P1001</id> stores it as a child element. Decide upfront that you want both as columns, and verify your chosen method captures attributes — some simple converters silently drop them.
Nesting depth
Two levels (catalog → product → name) flatten trivially. Five levels with mixed repeating groups need Power Query or Python, where you expand level by level and choose at each fork whether to explode into rows or join into one cell.
Namespaces
If tags look like <g:id> or the root declares xmlns, you have namespaces. Do not strip them with find-and-replace (a tempting hack that corrupts feeds with colliding tag names); instead use a namespace-aware tool — Power Query or Python with a namespace map.
Worked Example: Product Catalog XML to Spreadsheet
Let’s convert a small multi-category catalog, including attributes and a namespaced price — the realistic messy case:
<catalog xmlns:g="http://base.google.com/ns/1.0">
  <product id="P1001">
    <name>Wireless Mouse</name>
    <g:price currency="USD">29.99</g:price>
    <category>Peripherals</category>
    <category>Sale</category>
    <stock>340</stock>
  </product>
  <product id="P1002">
    <name>USB-C Hub</name>
    <g:price currency="USD">49.99</g:price>
    <category>Peripherals</category>
    <stock>120</stock>
  </product>
</catalog>
Power Query route: Data → Get Data → From File → From XML → click into product → Transform Data. Expand g:price to get value and currency columns. The category column holds a list — choose Expand to New Rows if you want one row per category (better for pivot tables) or Extract Values with a “; ” separator if you prefer one row per product. Set id to Text. Close & Load.
Result (exploded): three rows — P1001 appears twice (Peripherals, Sale), P1002 once — with columns id, name, g:price.value, g:price.currency, category, stock. The namespace prefix survives in the column name, which is harmless; rename it to price in the editor if you like tidy headers.
Troubleshooting XML Conversion Problems
Blank columns after import
Almost always namespaces or wrong-level mapping. In Power Query, navigate the Navigator tree slowly and preview each level; in XML Maps, verify the schema actually contains those elements. As a diagnostic, try a tiny test file with namespaces removed — if it works, namespaces are your culprit.
One giant row instead of many
You mapped the parent element instead of the repeating child. Re-map at the repeating level (see the worked example).
“Cannot load the specified XML” / schema errors
The XML may be malformed — an unclosed tag or a stray & (which must be written & in XML). Validate the file with a free XML validator before blaming Excel.
Special characters turn to gibberish
Encoding mismatch. Check the XML declaration (<?xml version="1.0" encoding="UTF-8"?>) and make sure the file is actually saved in that encoding. Re-save as UTF-8 in a proper editor (VS Code, Notepad++) rather than Windows Notepad’s default ANSI.
Numbers lose leading zeros
Set ID/SKU/code columns to Text during import — in the XML Map (via the mapped table’s column format), in Power Query’s type row, or with dtype=str in pandas. See our leading-zeros guide for the full story.
File too large to import
Excel struggles past a few hundred megabytes of XML. Stream it with Python’s iterparse, split it into chunks, or ask the source system for a filtered export. Remember the hard ceiling: 1,048,576 rows per worksheet.
Pro Tips for Clean XML Conversions
- Identify the repeating element first. Everything downstream depends on this one decision.
- Prefer the schema when you have it. An XSD gives Excel a perfect map and correct data types for free.
- Keep attributes. IDs, currencies, and language codes usually live in attributes — verify they survived.
- Decide explode-vs-join for every list. Explode for analysis, join for labels; document the choice in the workbook.
- Type text-like codes as Text on import. Repairing mangled IDs afterward is painful; preventing it is trivial.
- Validate before importing. A malformed XML file wastes more time in Excel errors than a 30-second validation costs.
- Save the query or the map. Recurring feeds should be one-click refreshes, not weekly rebuilds.
- Archive the source XML. Flattening choices are lossy; keep the original so you can re-flatten differently later.
Hit an XML feed with namespaces that refuse to expand no matter what you try? join the discussion in our community forum — feed-wrangling is a popular topic and someone has likely tamed your exact format.
Frequently Asked Questions
How do I open an XML file in Excel?
The easiest built-in way is Data → Get Data → From File → From XML, which uses Power Query. Alternatively, enable the Developer tab and use Source → XML Maps for a mapped, refreshable import with precise control over which element lands where.
Can I convert XML to XLSX online for free?
Yes. A free online xml to xlsx converter turns an XML file into an Excel workbook in your browser. For sensitive data, prefer a converter that processes files locally on your device so nothing is uploaded.
What is an XML Map in Excel?
An XML Map links XML elements to worksheet cells or table columns via the Developer tab. Once mapped, you can import XML data into those cells and refresh it whenever the source file changes — perfect for recurring feeds.
How do I handle repeating XML elements in Excel?
Map the repeating element to an Excel Table so each repetition becomes a row. In Power Query, expand the list column to new rows. In Python, iterate over the elements and build one DataFrame row per element.
Why does my XML import show blank columns?
Usually this is caused by XML namespaces or by mapping a parent element instead of the repeating child. In Power Query, drill into the correct record level before expanding, and check that namespace prefixes match the source.
Does Excel preserve XML attributes on import?
Yes. Power Query exposes attributes as fields, and XML Maps let you drag attributes into cells. If a simple converter drops your attributes, switch to Power Query or Python, which both handle them properly.